Frontier open-weight LLMs, hosted on the NRP
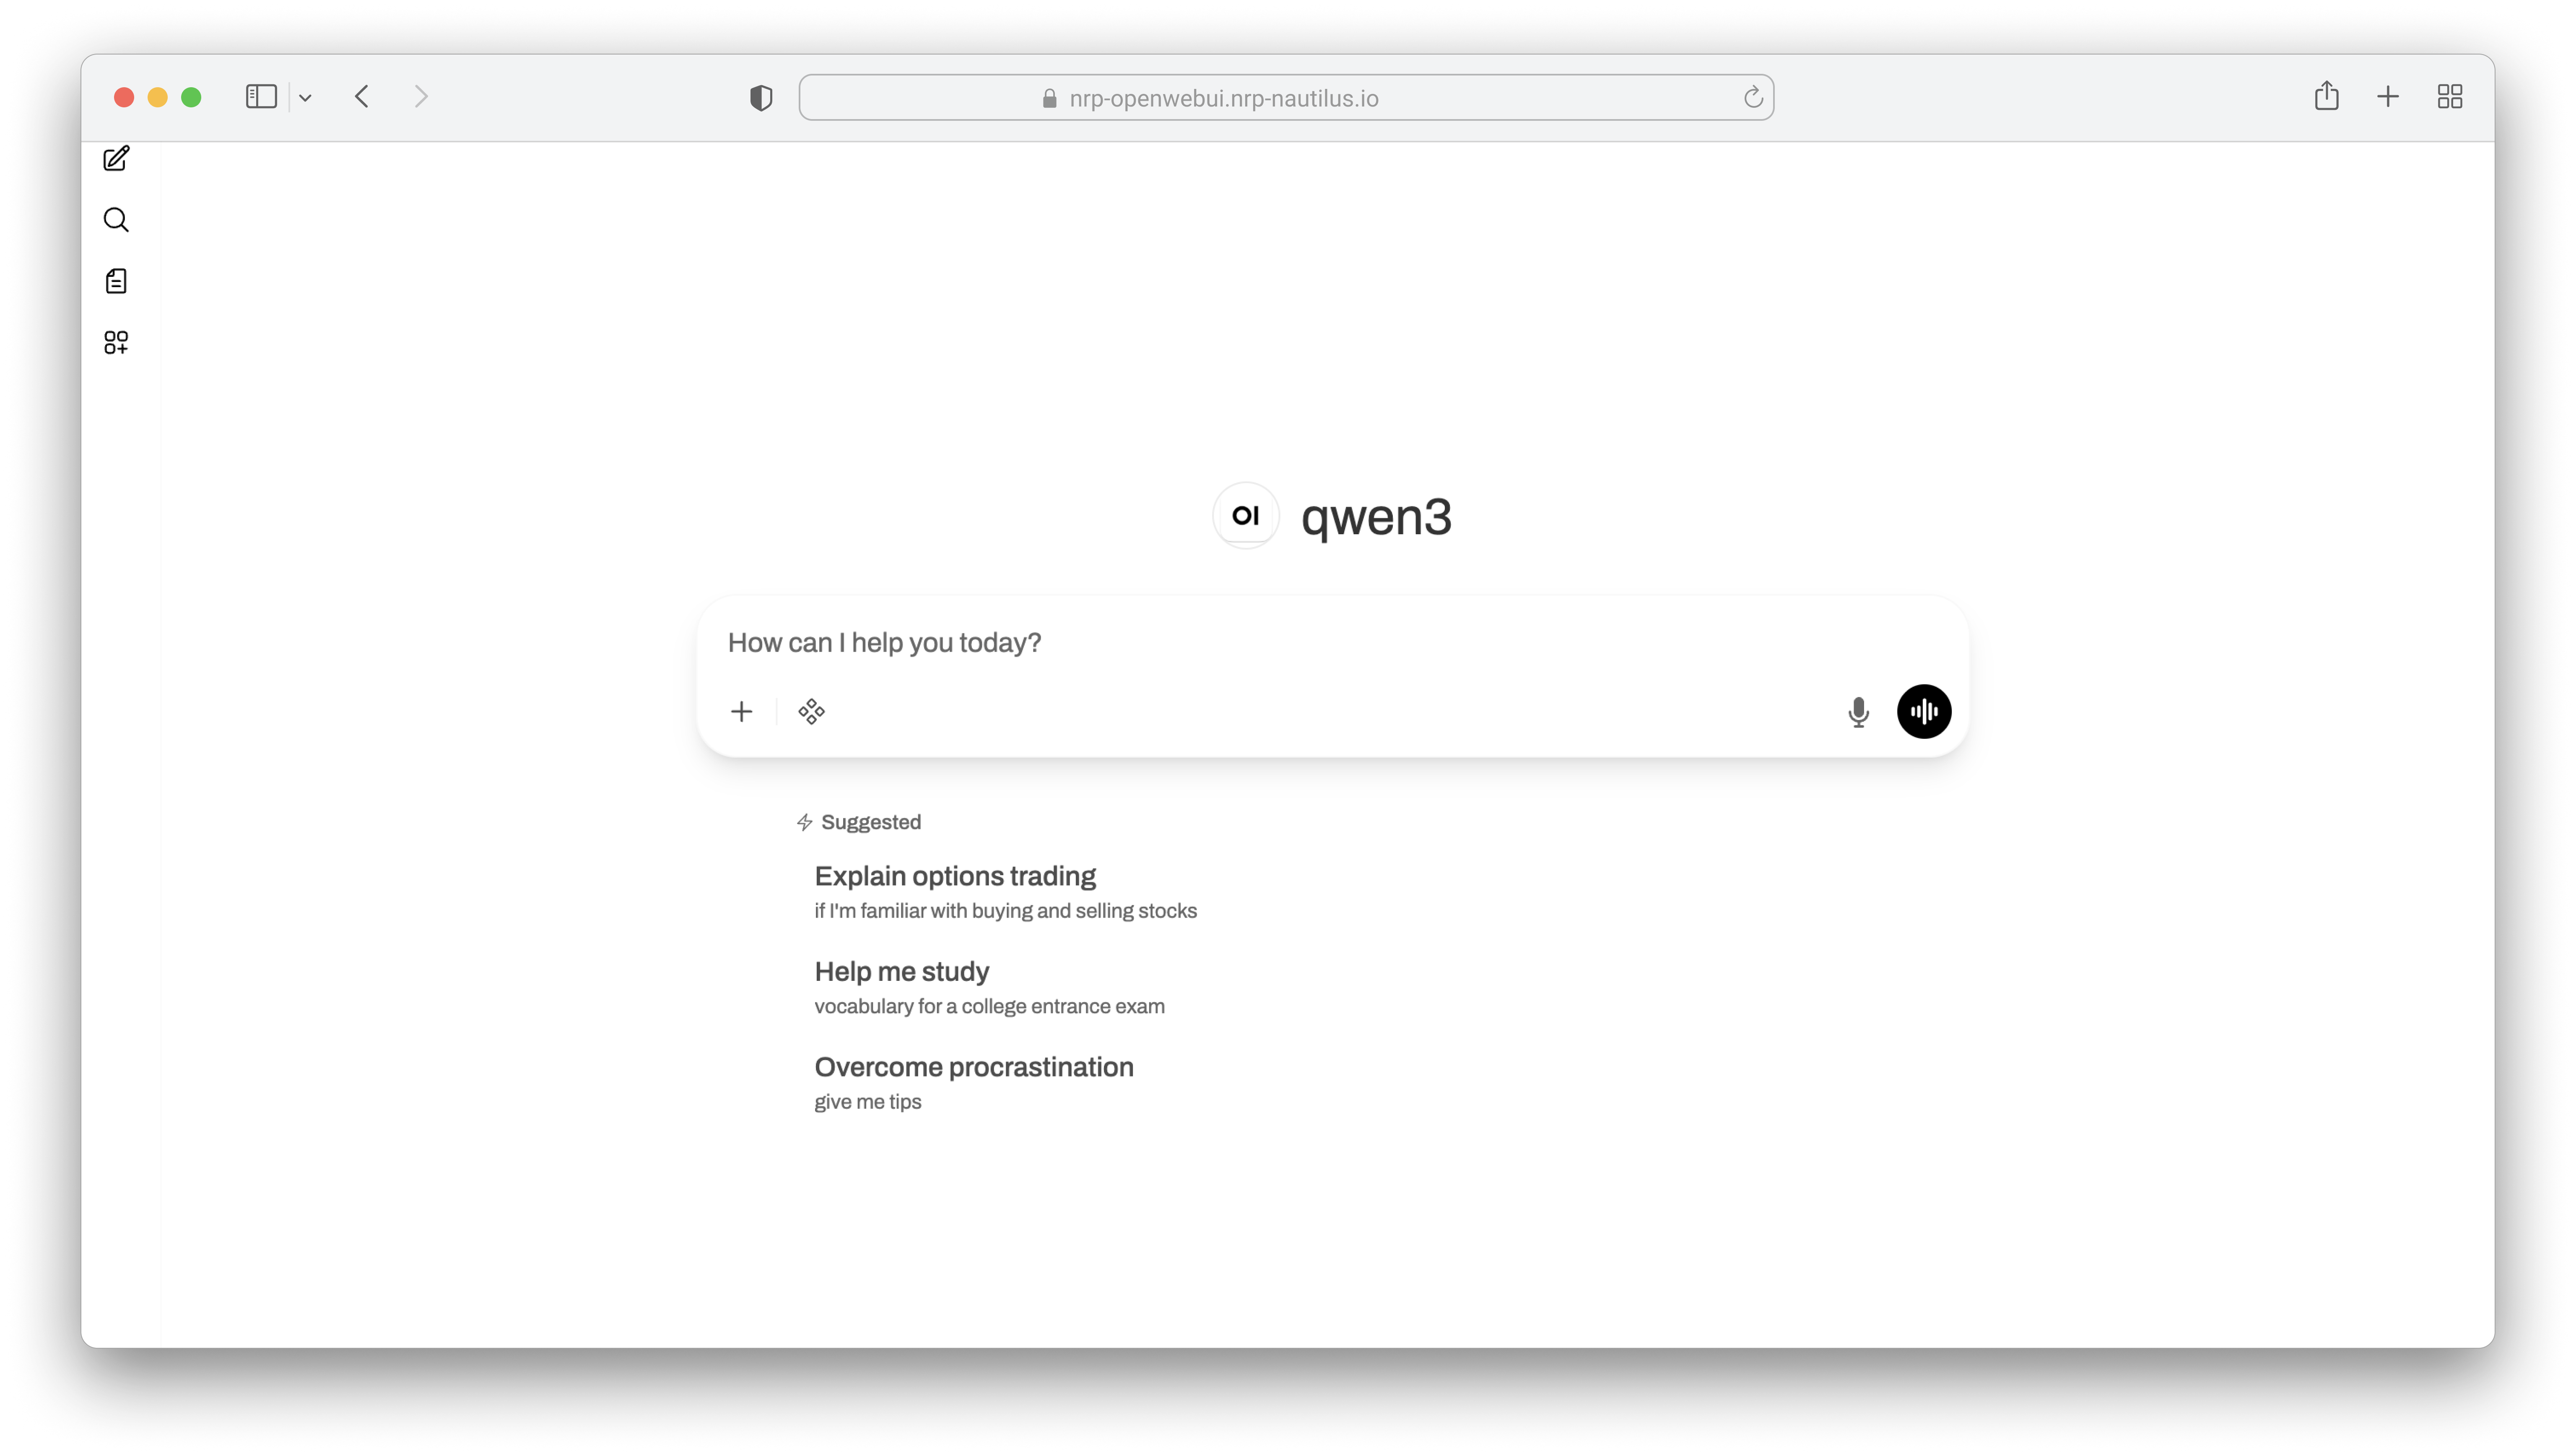
Free access for researchers and educators to a rotating catalog of frontier open-weight models — through a hosted chat interface, ready-made coding-CLI configs, and an OpenAI-compatible API with no per-token billing, from single chats to batch runs over whole corpora.
What you can use them for
The same endpoint carries a chat window, a coding agent, the platform's own operations, and corpus-scale batch jobs — none of it billed by the token.
Document understanding and sentiment
Researchers can parse and summarize large document collections, then extract signals such as sentiment from sources like securities filings.
Agentic coding for classrooms and research groups
Classrooms and research groups can use coding agents with NRP-hosted models to develop, review, and iterate on software projects.
Batch LLM processing
No per-token billing and no cap on how many requests you send: point a script at the API and work through whole document corpora, eval sweeps, or synthetic-data jobs. Fair use governs how many requests run at once — never how many you make.
Agentic operations
The platform turns its own operations over to the models it hosts: operators question failing nodes, users untangle problem pods, and the accounting system answers in plain language.
- nodes
- Query and diagnose failing infrastructure in the context of the cluster it runs.
- pods
- Inspect logs, events, and related pod details to troubleshoot a workload.
- accounting
- An MCP server connects models to the NRP accounting system to surface usage insights.
How to get access
Step 1: Get an NRP account
Sign in once with your institutional or research identity to register a Nautilus account.
Step 2: Request an LLM-enabled namespace
Fill out the namespace request form and check the hosted-LLM option so its members can mint API keys. Already have a namespace? Ask in the support chat to enable LLM access on it.
Step 3: Generate your LLM API key
Use the LLM API Keys page to create a personal API key, then plug it into Open WebUI, Chatbox, or any OpenAI-compatible client.
Models we host
Frontier open-weight models with strong reasoning, coding, and multimodal capabilities. Pick the one that fits your task.
qwen3
180B (6B active) · 1M ctx
Flagship frontier multimodal MoE — a Qwen4-architecture preview, with image and video input and a million-token context window.
qwen3-small
27B · 1M ctx
Compact Qwen3.8 — multimodal, agentic, low-latency.
gpt-oss
120B · 131K ctx
OpenAI's open-weights agentic model — tiny GPU footprint, strong tools, LTS candidate.
gemma
31B · 262K ctx
Google's Gemma 4 — multimodal, efficient frontier performance.
gemma-small
12B · 262K ctx
evaluatingTiny Gemma 4 with unique audio input — ASR and speech-to-text on a 12B model.
kimi
1T · 131K ctx
evaluatingMoonshot's 1T-parameter coding-tuned model with image input.
glm-5
753B · 1M ctx
evaluatingZ.ai's 753B frontier coding model with NVFP4 weights — the catalog's highest Terminal-Bench 4.0 score, and second on Artificial Analysis' Intelligence Index.
deepseek-v4-flash
552B (16B active) · 1M ctx
evaluatingDeepSeek V4.1 Flash — the catalog's highest Artificial Analysis Intelligence Index, image input, and a full million-token context window.
minimax
428B (23B active) · 1M ctx
evaluatingMiniMax's 428B MoE with sparse attention in every layer — image and video input and a full million-token context window.
qwen3-embedding
8B · 262K ctx
Multimodal embedding model for retrieval and vector search — not a chat model.
Use the client you already have
Hosted chat interfaces, desktop apps, and coding CLIs all work with NRP-hosted LLMs through the OpenAI-compatible endpoint.
https://ellm.nrp-nautilus.io/v1 Requests authenticate with a personal API key as a bearer token — mint one on the LLM API Keys page once your namespace has LLM access enabled.
Ready to get started?
We will get you onto NRP-hosted LLMs and answer any questions about access, namespaces, and API keys.